Press Space to continue
We rebuilt how MoE models generate tokens on Blackwell GPUs
Press Space to continue
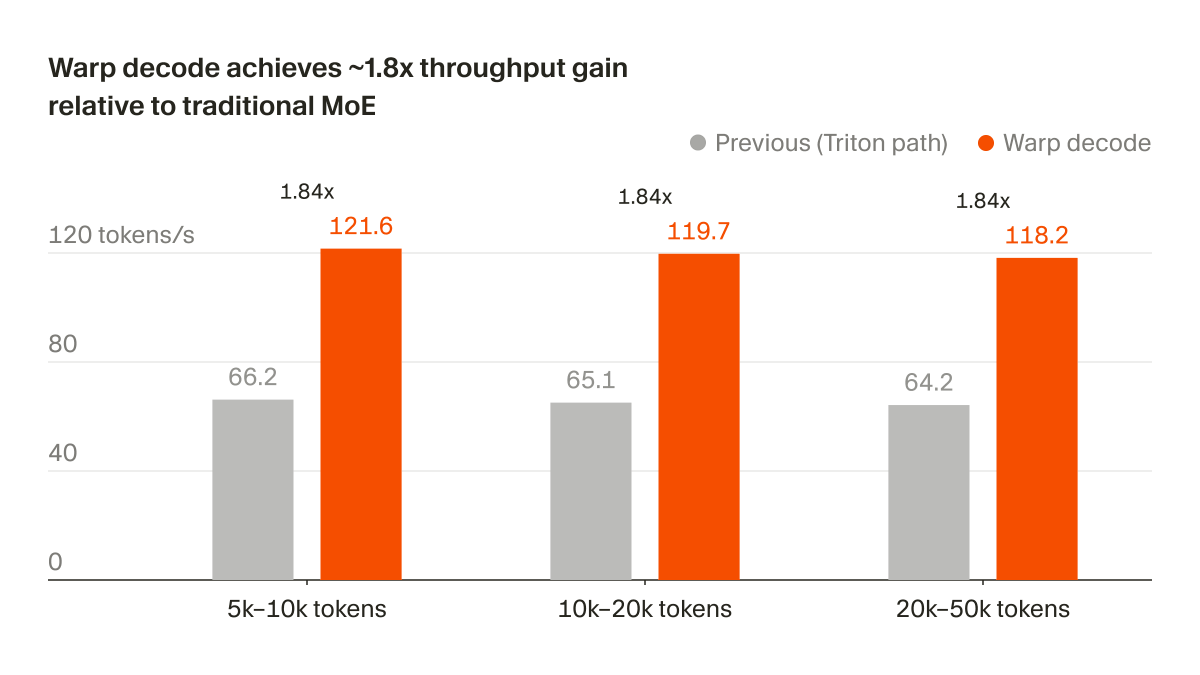
We rebuilt how MoE models generate tokens on Blackwell GPUs, resulting in 1.84x faster inference and more accurate outputs. These improvements directly contribute to how we train Composer, allowing us to ship improved versions of the model more often.
open on xViews and clicks count once per visitor per day. Clicks are opens of this post on X.