Press Space to continue
Apple's Feature Auto-Encoder enables 7x faster diffusion image
Press Space to continue
Apple researchers introduced Feature Auto-Encoder (FAE), a diffusion image generator that learns from compressed embeddings produced by a pretrained vision model. By shrinking rich embeddings before reconstruction, the system trains up to seven times faster while maintaining image quality comparable to state-of-the-art diffusion models. Read our summary of the paper in The Batch: https://hubs.la/Q047M-gw0
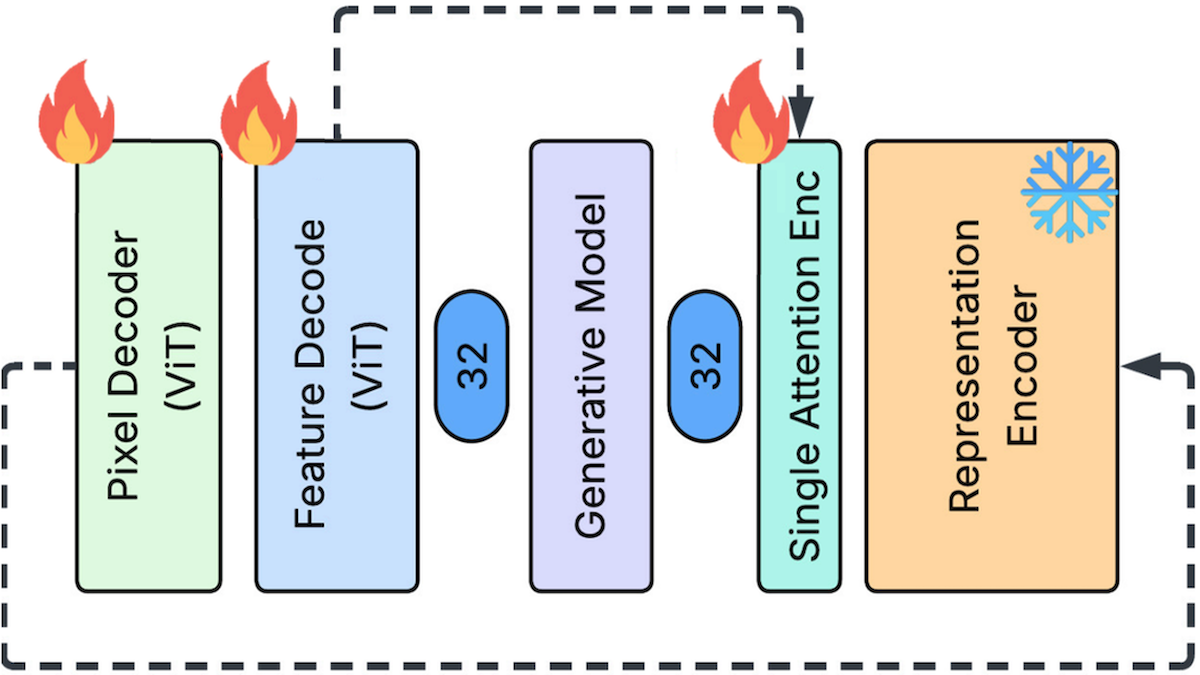
Inside Feature Auto-Encoder, a Diffusion Image Generator That Shrinks Embeddings for More Speed
open on xViews and clicks count once per visitor per day. Clicks are opens of this post on X.