Press Space to continue
Small language models are becoming stronger at reasoning
Press Space to continue
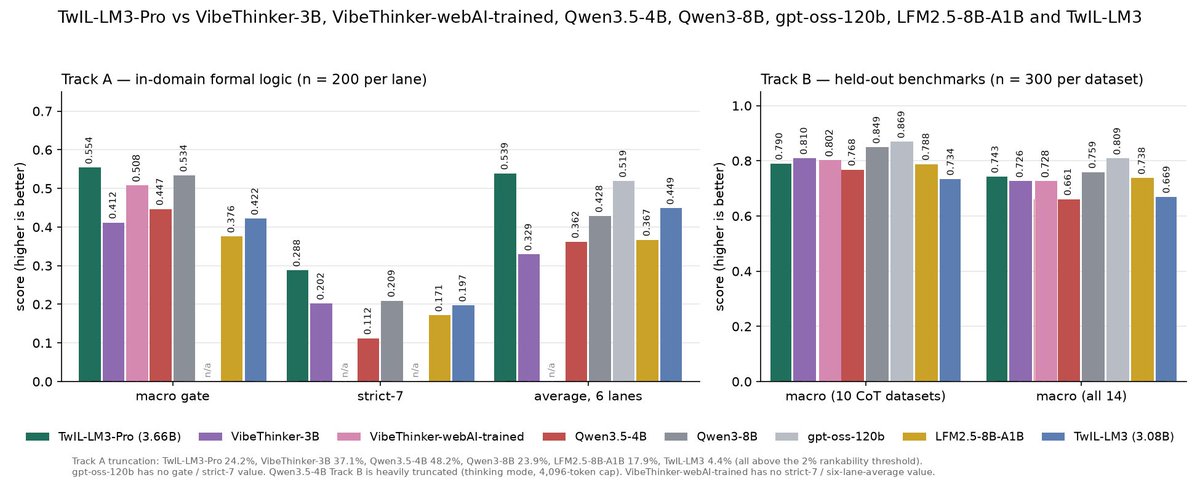
Small models are getting really good at reasoning. It's exciting because SLMs can unlock so much at the harness layer. TwIL-LM3-Pro from @thewebAI has 3.6B parameters and runs locally on everyday computers. It scores 95.4 on BIG-Bench Hard, well ahead of Qwen3-8B at 63.7. I like their post-training recipe. They fine-tune on formal logic, merge the weights back toward the base model, and then run RL against a programmatic verifier. Logic scores go up, and general reasoning holds…
open on x · 2 viewsViews and clicks count once per visitor per day. Clicks are opens of this post on X.