Press Space to continue
SWE-Bench Verified Has Flawed Tests and Data Leakage
Press Space to continue
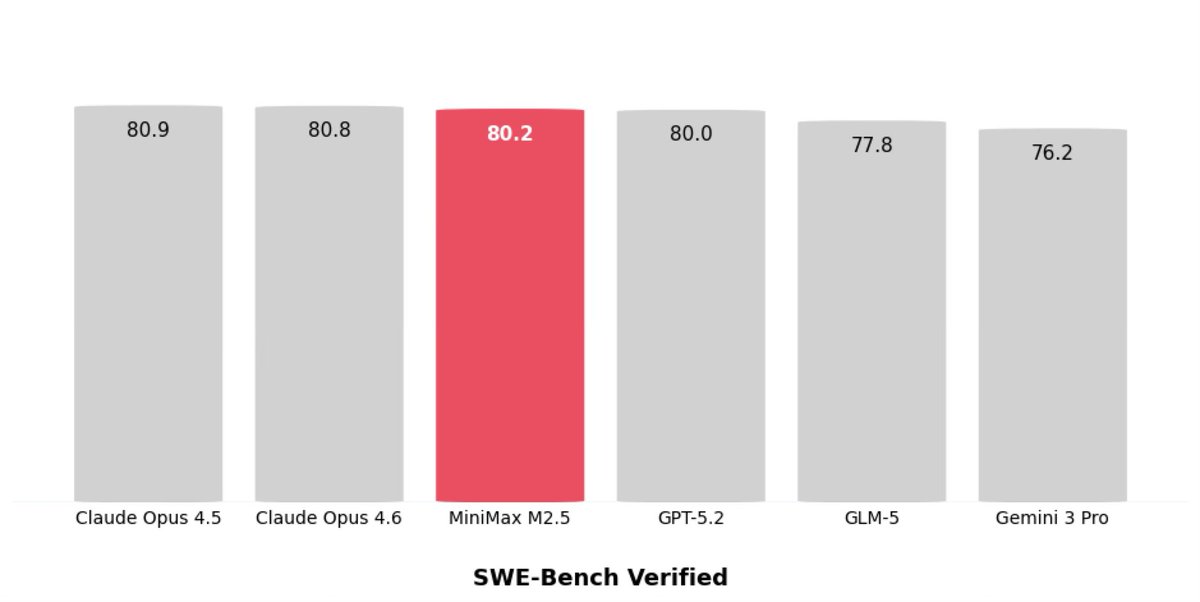
Am currently putting together an article, and yeah, the SWE-Bench Verified numbers are definitely a bit sus across all models -- the benchmark suggest they are more similar than they really are. So, I went down a rabbit hole looking into SWE-Bench Verified issues... And it looks like OpenAI already did really nice work there in their "Why SWE-bench Verified no longer measures frontier coding capabilities" analysis: https://openai.com/index/why-we-no-longe… The…
open on x · 2 viewsViews and clicks count once per visitor per day. Clicks are opens of this post on X.