Press Space to continue
RL mostly changes which reasoning strategies LLMs prefer
Press Space to continue
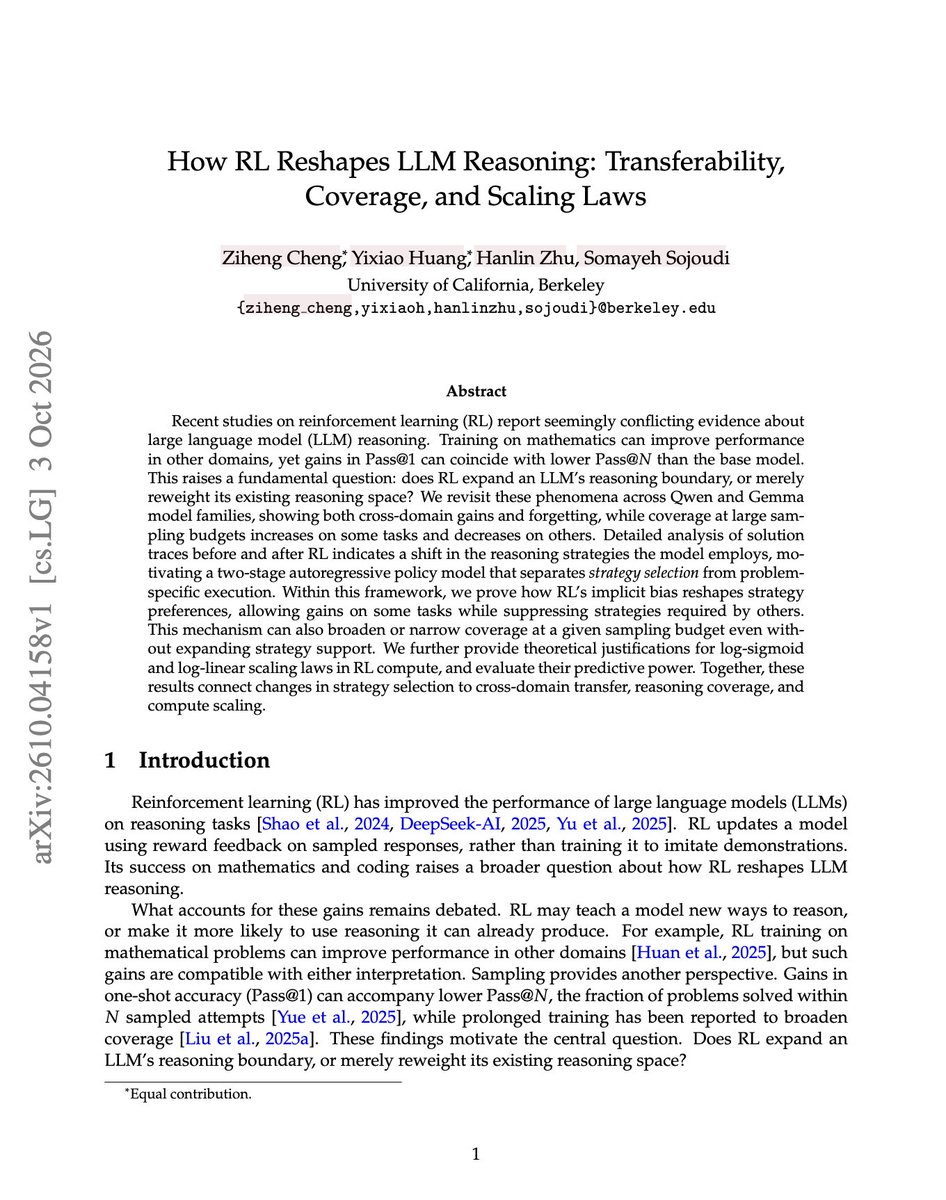
"How RL Reshapes LLM Reasoning: Transferability, Coverage, and Scaling Laws" Does RL actually teach LLMs new reasoning skills or just make them better at using the ones they already have? This paper suggests RL primarily changes which reasoning strategies models prefer. So by reinforcing certain approaches, it can improve accuracy on some tasks while suppressing useful strategies for others, and potentially reducing reasoning diversity. On Qwen3-14B, RL reduces reasoning strategy diversity…
open on xViews and clicks count once per visitor per day. Clicks are opens of this post on X.