Press Space to continue
Linear Attention Gets 3D Tensors for Longer Memory
Press Space to continue
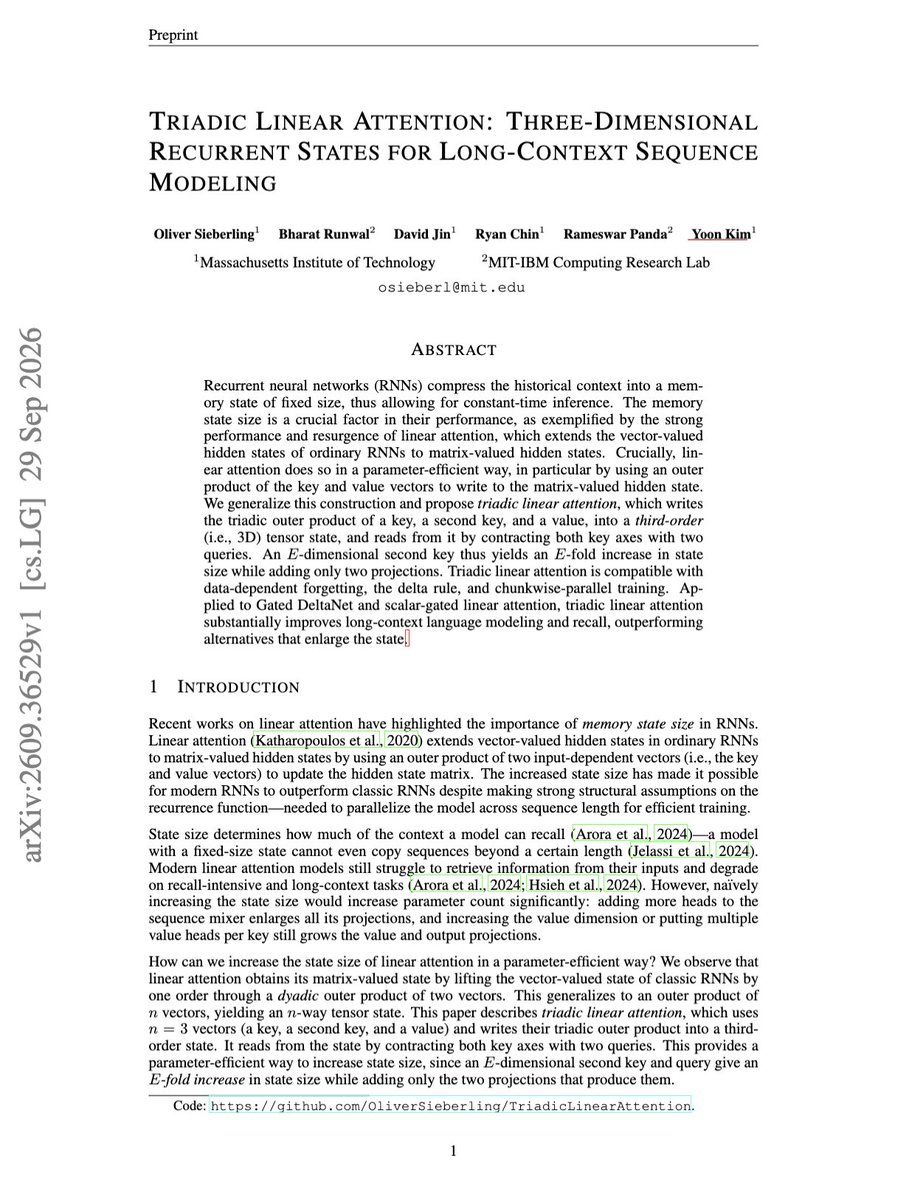
"Triadic Linear Attention: Three-Dimensional Recurrent States for Long-Context Sequence Modeling" Linear attention is fast, but its fixed-size state limits memory. This paper expands that matrix into a 3D tensor using two keys, giving an 8x larger recurrent state with only ~1.2% more parameters. At 1.3B scale, it improves long-context recall and reaches 5.1x Transformer speed at 64k context. https://alphaxiv.org/abs/2609.36529
open on x · 1 viewViews and clicks count once per visitor per day. Clicks are opens of this post on X.