Press Space to continue
Alignment Training Narrows Language Models to Familiar Outputs
Press Space to continue
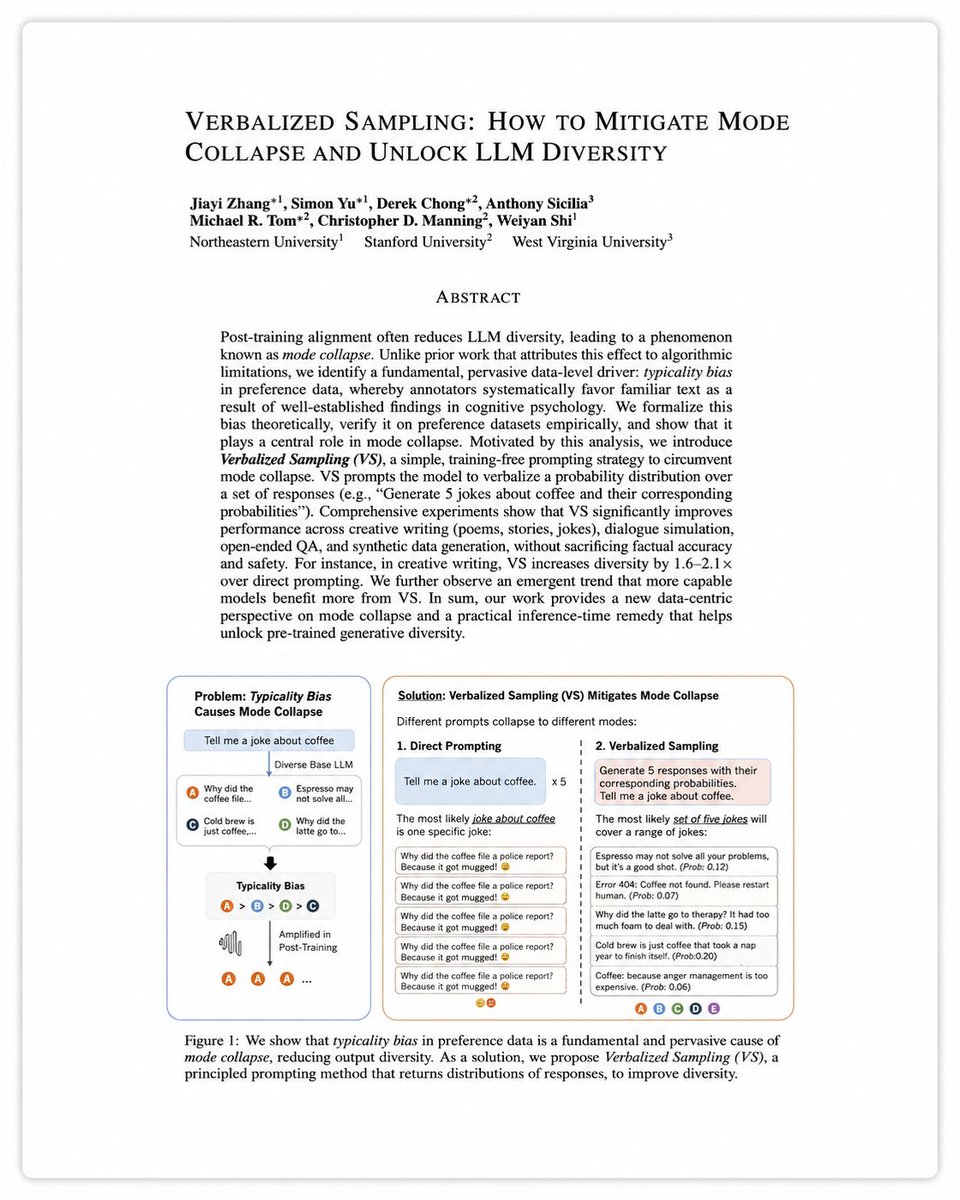
Ask ChatGPT for 5 different jokes. You'll get nearly the same joke 5 times. A new paper from Northeastern, Stanford, and West Virginia (Christopher Manning is on the author list) just identified the cause and shipped a one-line prompt fix. After RLHF or DPO, aligned models feel narrower than the base models they came from. Same jokes. Same metaphors. Same structures. The paper goes to the preference data. When annotators pick between two model outputs, they systematically favor the more…

open on x · 2 viewsViews and clicks count once per visitor per day. Clicks are opens of this post on X.