Press Space to continue
AI clinical reasoning study reveals 90%+ diagnostic accuracy
Press Space to continue
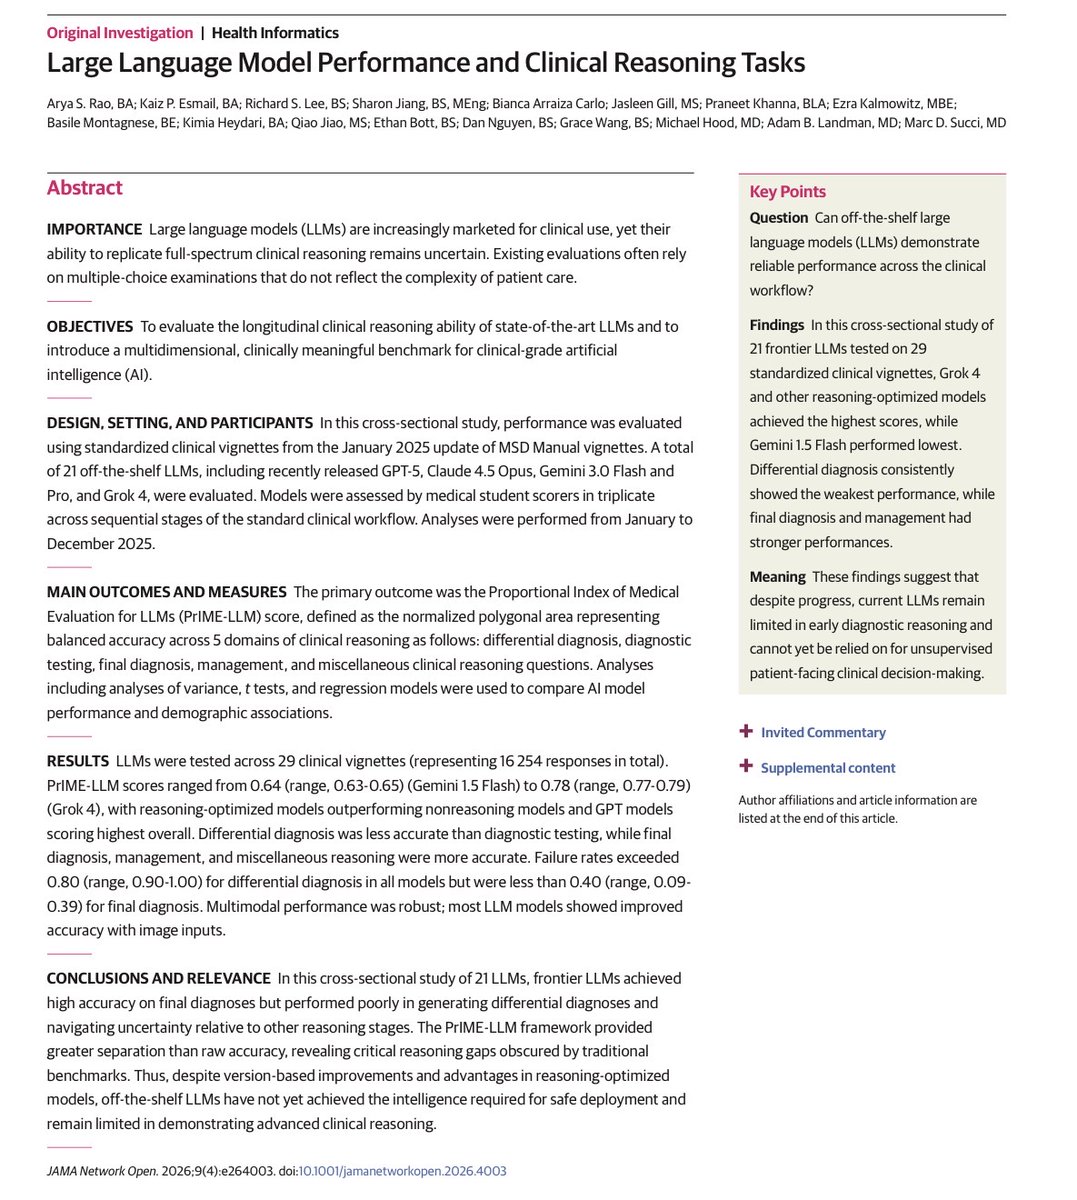
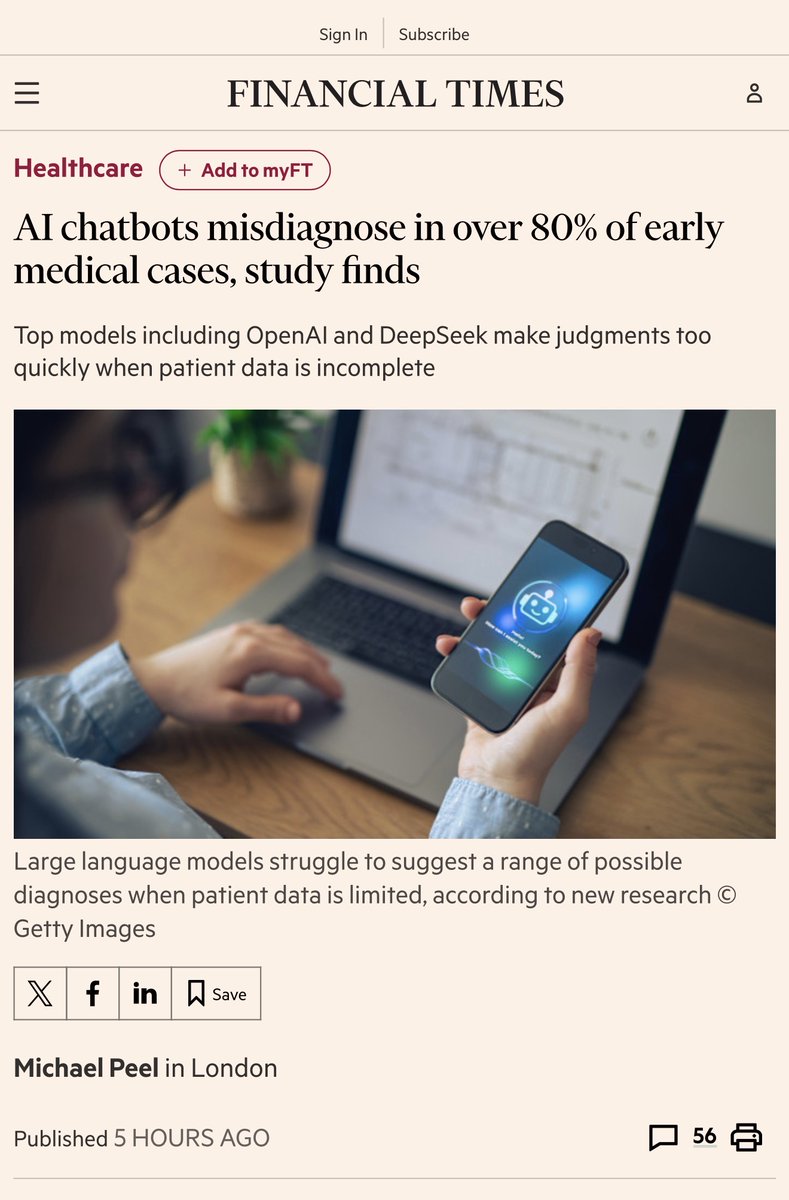
Mass General Brigham just published the largest clinical reasoning study of AI models ever. The FT headline says 80% misdiagnosis. The paper says 90%+ accuracy on final diagnosis. Both are true. The gap between those numbers is where all of medicine actually happens. The study, published today in JAMA Network Open, tested 21 frontier LLMs including GPT-5, Claude 4.5 Opus, Gemini 3.0, and Grok 4 on 29 standardized clinical cases. Each model was fed patient information in stages, the same way a…
open on x · 2 viewsViews and clicks count once per visitor per day. Clicks are opens of this post on X.