Press Space to continue
AI Model Outperforms Doctors on Medical Benchmarks and ER Cases
Press Space to continue
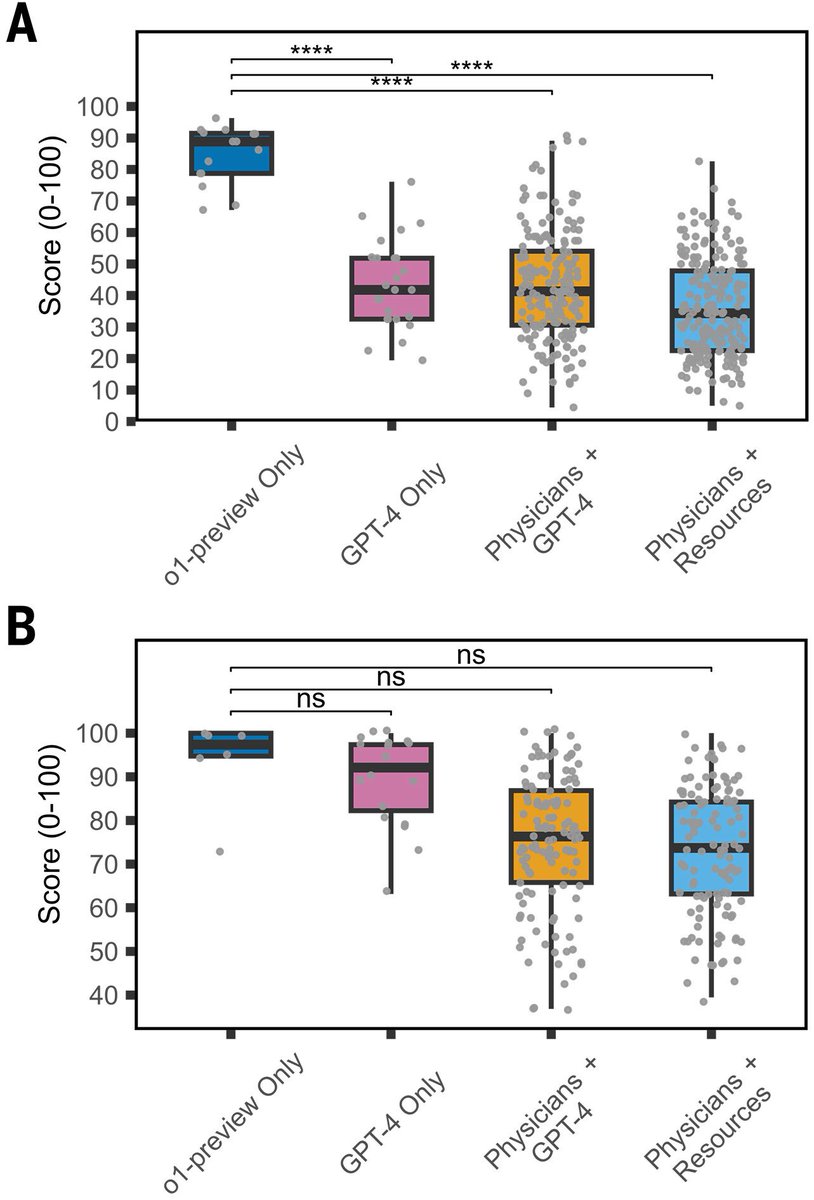
New paper (on an old AI) tests o1 against doctors on medical benchmarks & real ER cases: “across a variety of scenarios and applications, the large language model outperformed both human physicians and older models” The potential suggests an “urgent need for prospective trials.”


open on x · 2 viewsViews and clicks count once per visitor per day. Clicks are opens of this post on X.