Press Space to continue
Block Sparse Attention Achieves Log-Linear Complexity
Press Space to continue
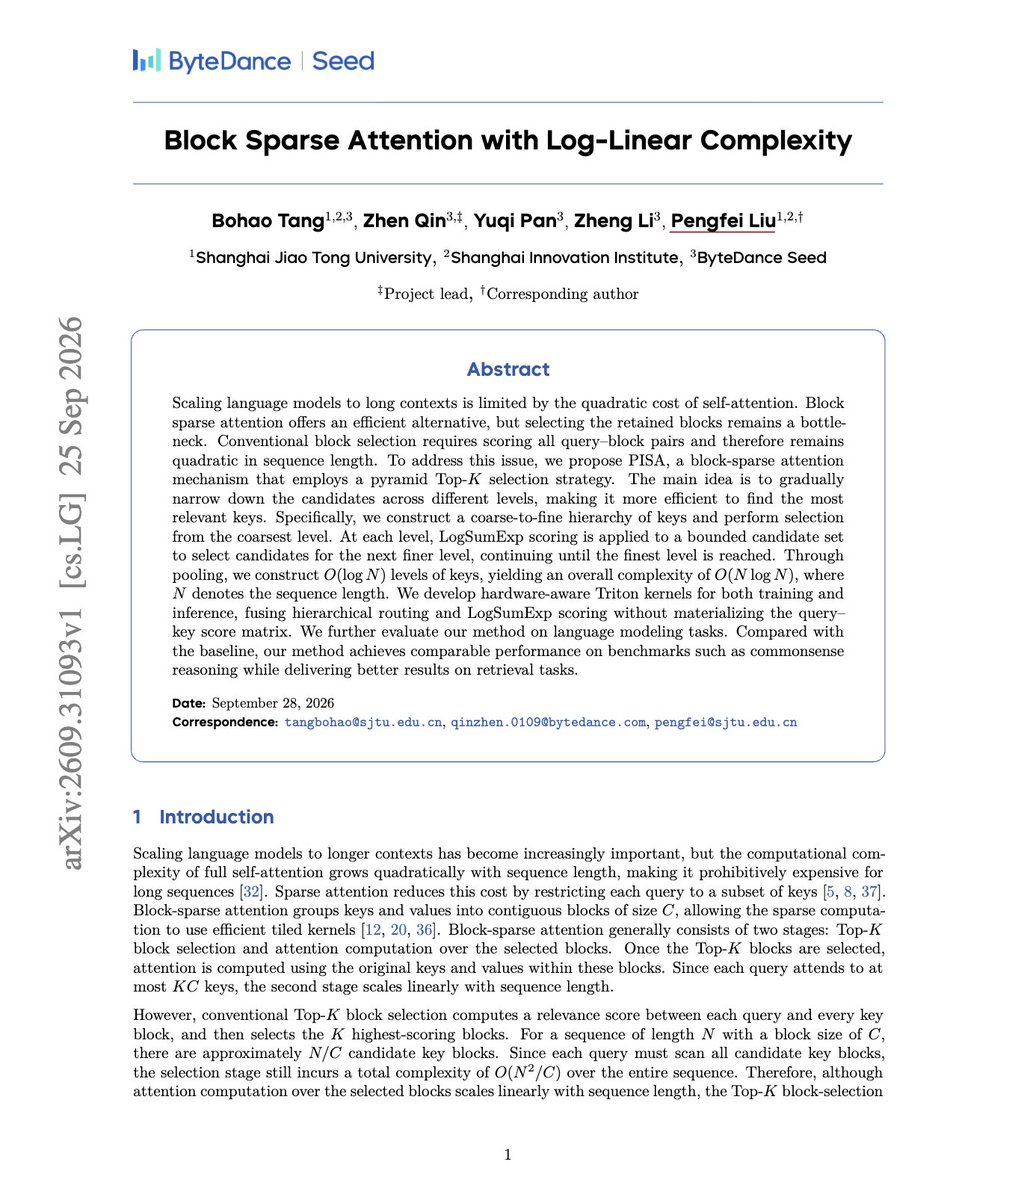
"Block Sparse Attention with Log-Linear Complexity" Most block-sparse attention still has a hidden quadratic bottleneck because every query has to score lots of candidate blocks before deciding which ones to keep. This paper fixes this by first checking large regions of the context, keeps only the most promising ones, then recursively zooms into those regions using LogSumExp scores. That cuts block selection from O(N^2) to O(N log N). At 256K context, routing is 9.95x faster than standard…
open on x · 3 views · 1 clickViews and clicks count once per visitor per day. Clicks are opens of this post on X.