Cognition@cognition3h ago
Introducing FrontierCode 2.0: our new coding benchmark that measures a model’s ability to go beyond the spec.
Most coding evals measure a model’s ability to write code that meets a spec. With FrontierCode 1.0, we asked a new question: would you actually merge the PR?
FrontierCode 2.0 is comprised of more diverse tasks, featuring larger scopes and higher mergeability standards. We are now asking: not only would you merge this PR, but should you?
One key feature of FrontierCode 2.0 is underspecified prompts. Rather than including every engineering decision, prompts are deliberately ambiguous, giving the models room to demonstrate their judgment.
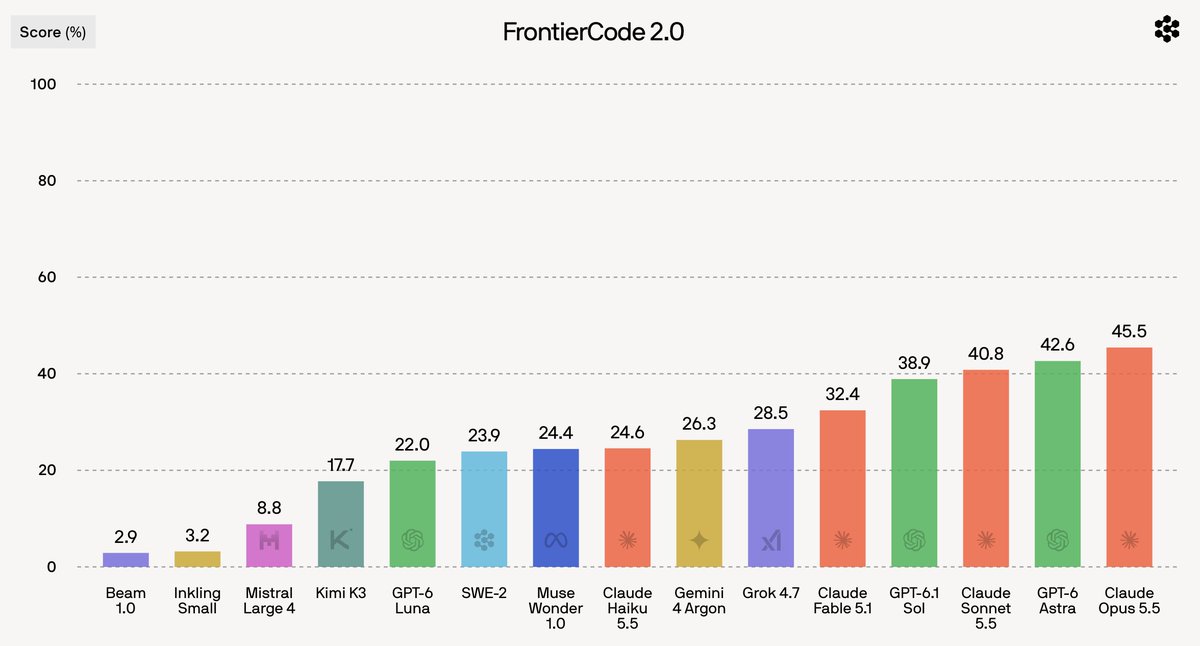
The result is a benchmark that is far from saturated, with the top model scoring just 45%.