Press Space to continue
Error bars matter more than ranking positions
Press Space to continue
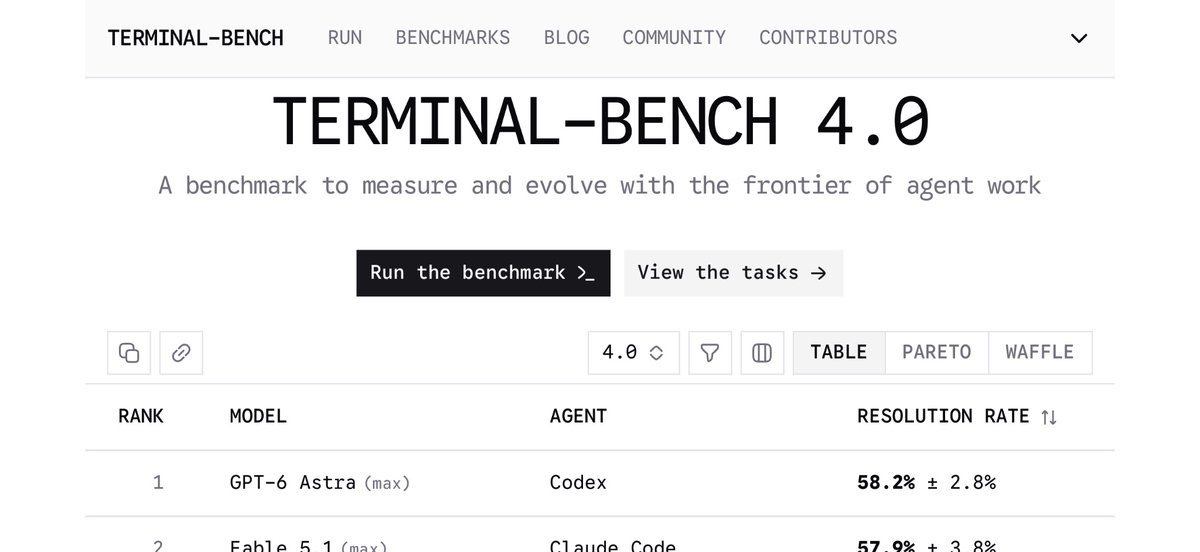
Read the error bars before the ranking. GPT-6 Astra in Codex: #1 at 58.2% +/- 2.8 Fable 5.1 in Claude Code: #2 at 57.9% +/- 3.8 A 0.3-point gap, inside error bars of 2.8 and 3.8. That's a tie on accuracy. The cost is the number in this tweet that matters. Half the price for the same score. And much of that cost comes from the harness: how many turns the loop needs, how much context gets loaded each turn, and when the agent decides it's done. Cline demonstrated this in July. Same model, only…
open on x · 2 viewsViews and clicks count once per visitor per day. Clicks are opens of this post on X.