Press Space to continue
Apple's AToken unifies image
Press Space to continue
Apple introduced AToken, a model that uses a shared tokenizer and encoder to process and generate images, videos, and 3D objects in one unified framework. The multimodal approach beats or rivals specialized models in performance and helps transfer knowledge transfer across media types, potentially reducing training data needs and improving applications. Read our summary of the paper in The Batch: https://hubs.la/Q048Hp-v0
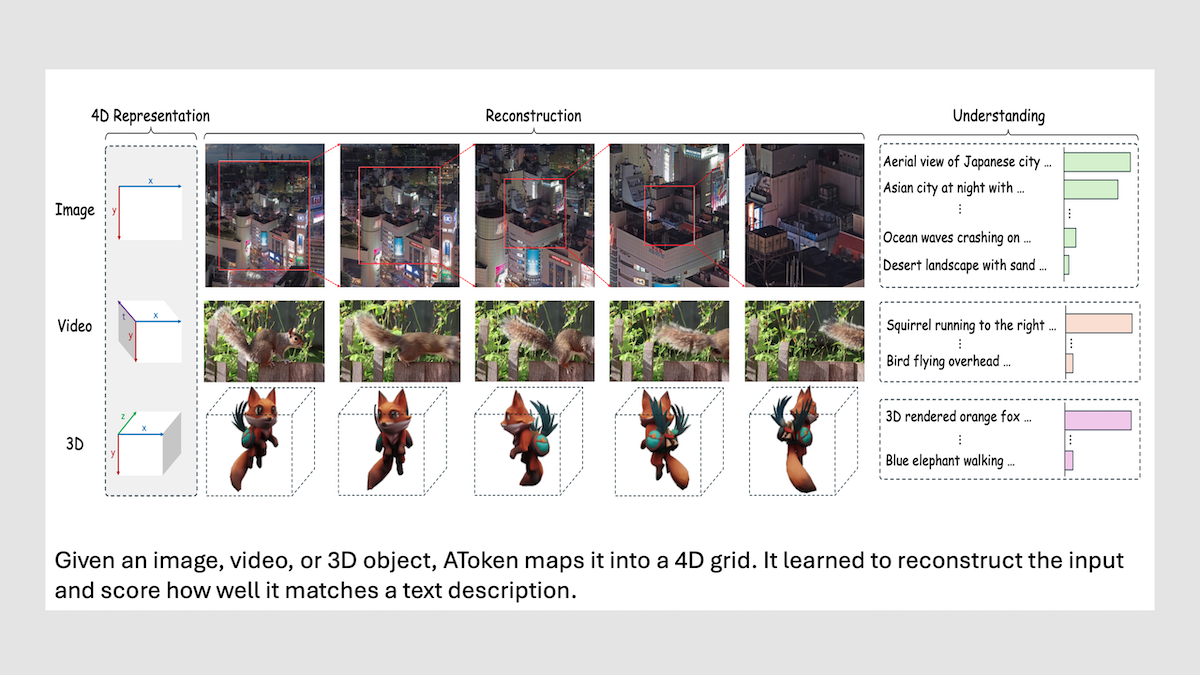
Apple’s AToken, a Multimodal Model with a Single Encoder and Tokenizer for Images, Videos, and 3D Objects
open on xViews and clicks count once per visitor per day. Clicks are opens of this post on X.