Press Space to continue
Post-training quantization works effectively on large language
Press Space to continue
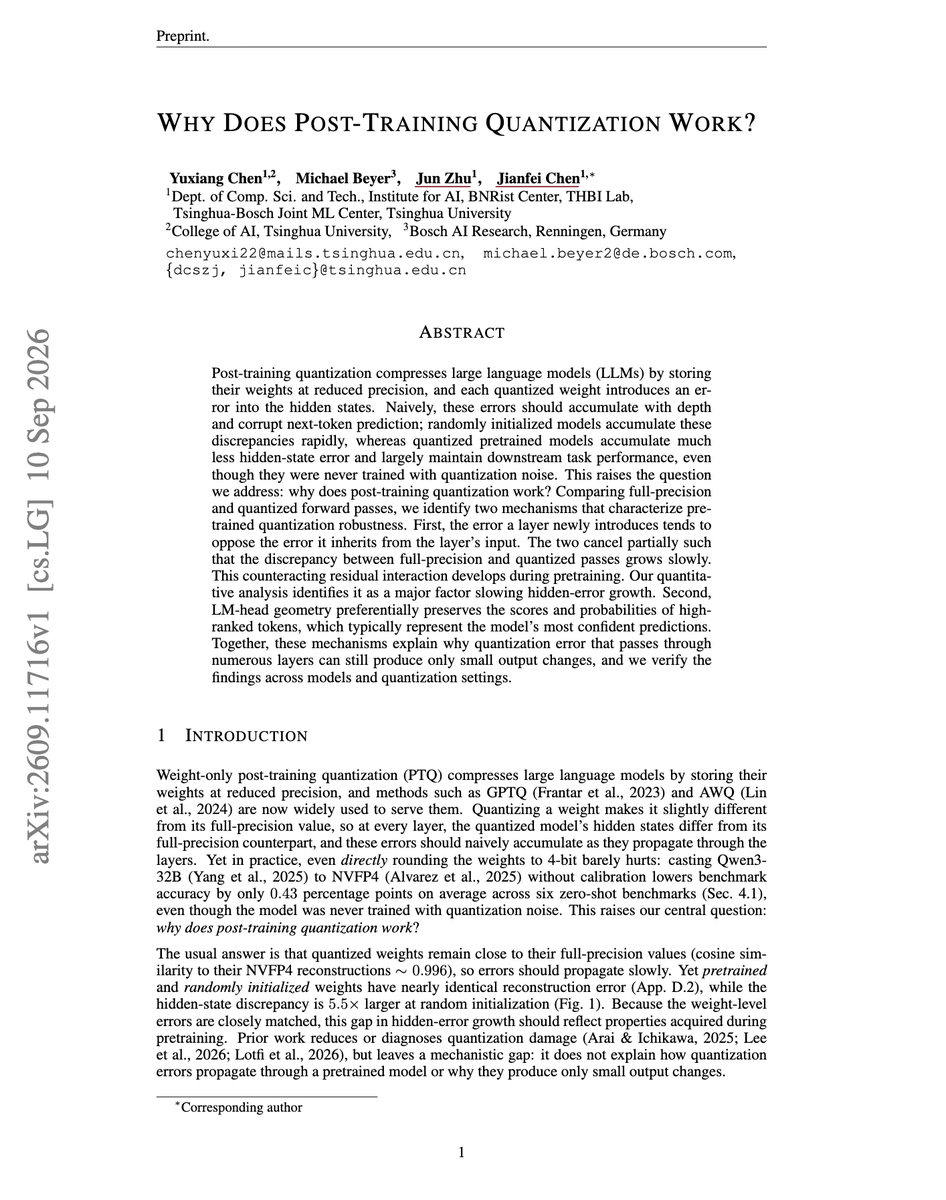
“Why Does Post-Training Quantization Work?” This paper shows that pretrained LLMs are inherently robust to quantization because layers actively counteract accumulated quantization errors, while high-dimensional LM-head geometry preferentially preserves top-token predictions. This lets 4-bit models stay close to full precision despite substantial hidden-state perturbations. https://alphaxiv.org/abs/2609.11716
open on x · 1 viewViews and clicks count once per visitor per day. Clicks are opens of this post on X.