Press Space to continue
Looped Diffusion Transformer Matches Larger Models
Press Space to continue
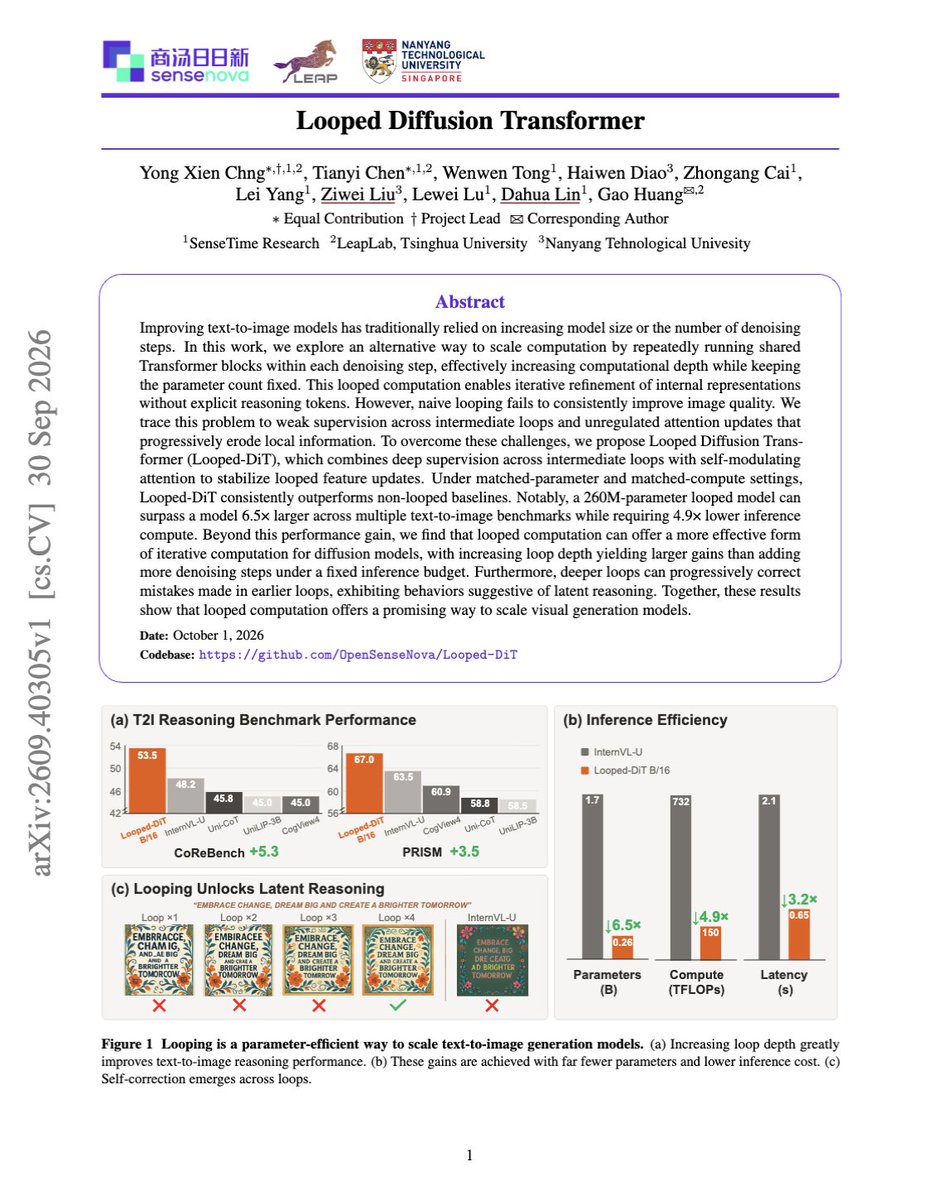
"Looped Diffusion Transformer" This new paper reuses the same Transformer blocks multiple times within each denoising step, repeatedly updating the hidden state to improve the prediction without increasing the model’s parameter count at inference-time. The found that a 260M model beats models up to 6.5x larger, and extra loops improve performance more than spending the same compute on extra denoising steps. https://alphaxiv.org/abs/2609.40305
open on x · 2 viewsViews and clicks count once per visitor per day. Clicks are opens of this post on X.