Press Space to continue
Voice isolation reduces speech-to-text errors by 73 percent
Press Space to continue
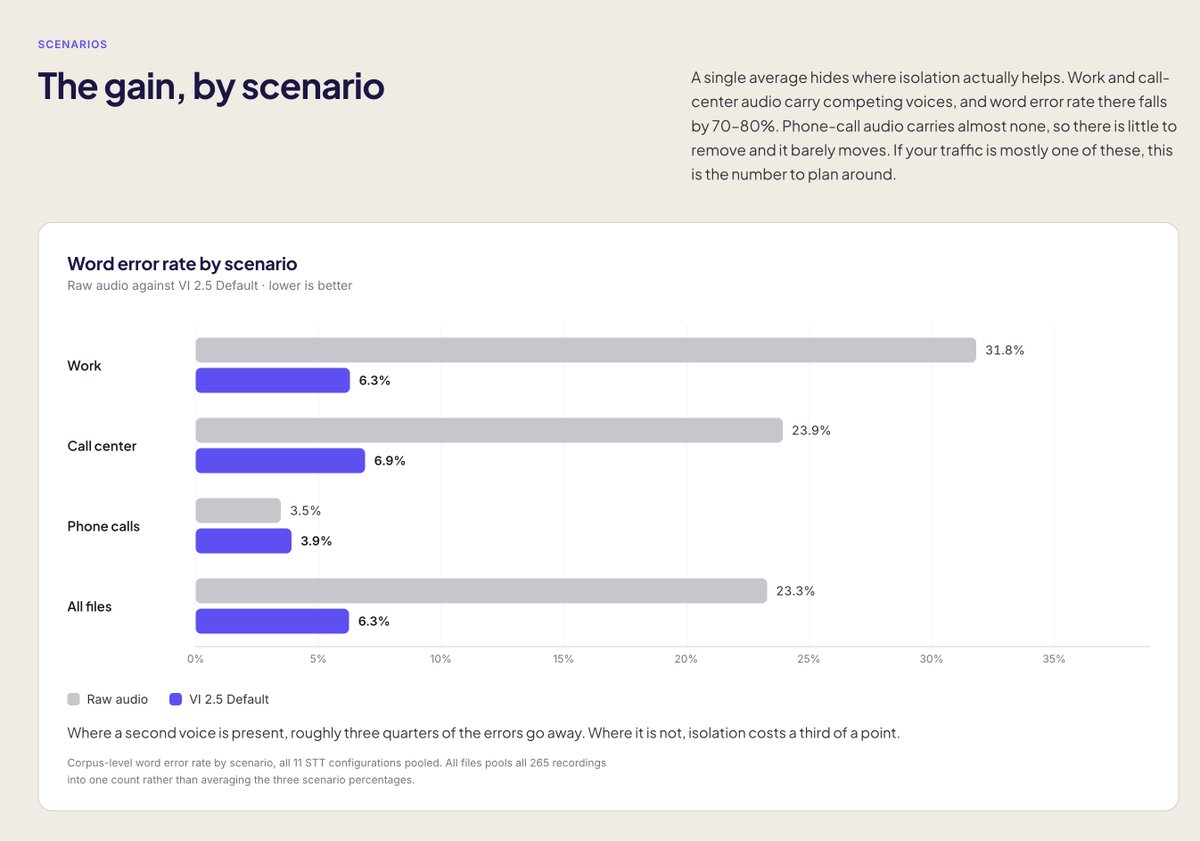
Cutting down noise before sending the audio to a speech-to-text model makes a huge improvement. Voice isolation is the next big thing you want to pay attention to. Krisp just released an open benchmark and a dataset to measure the impact of voice isolation on STT accuracy. The results are eye-watering: 73% reduction in WER across 265 real recordings and 11 speech-to-text configurations. This compares an original recording with a voice-isolated version. Here are the results with voice…
open on x · 2 viewsViews and clicks count once per visitor per day. Clicks are opens of this post on X.