Press Space to continue
The harness—the framework
Press Space to continue
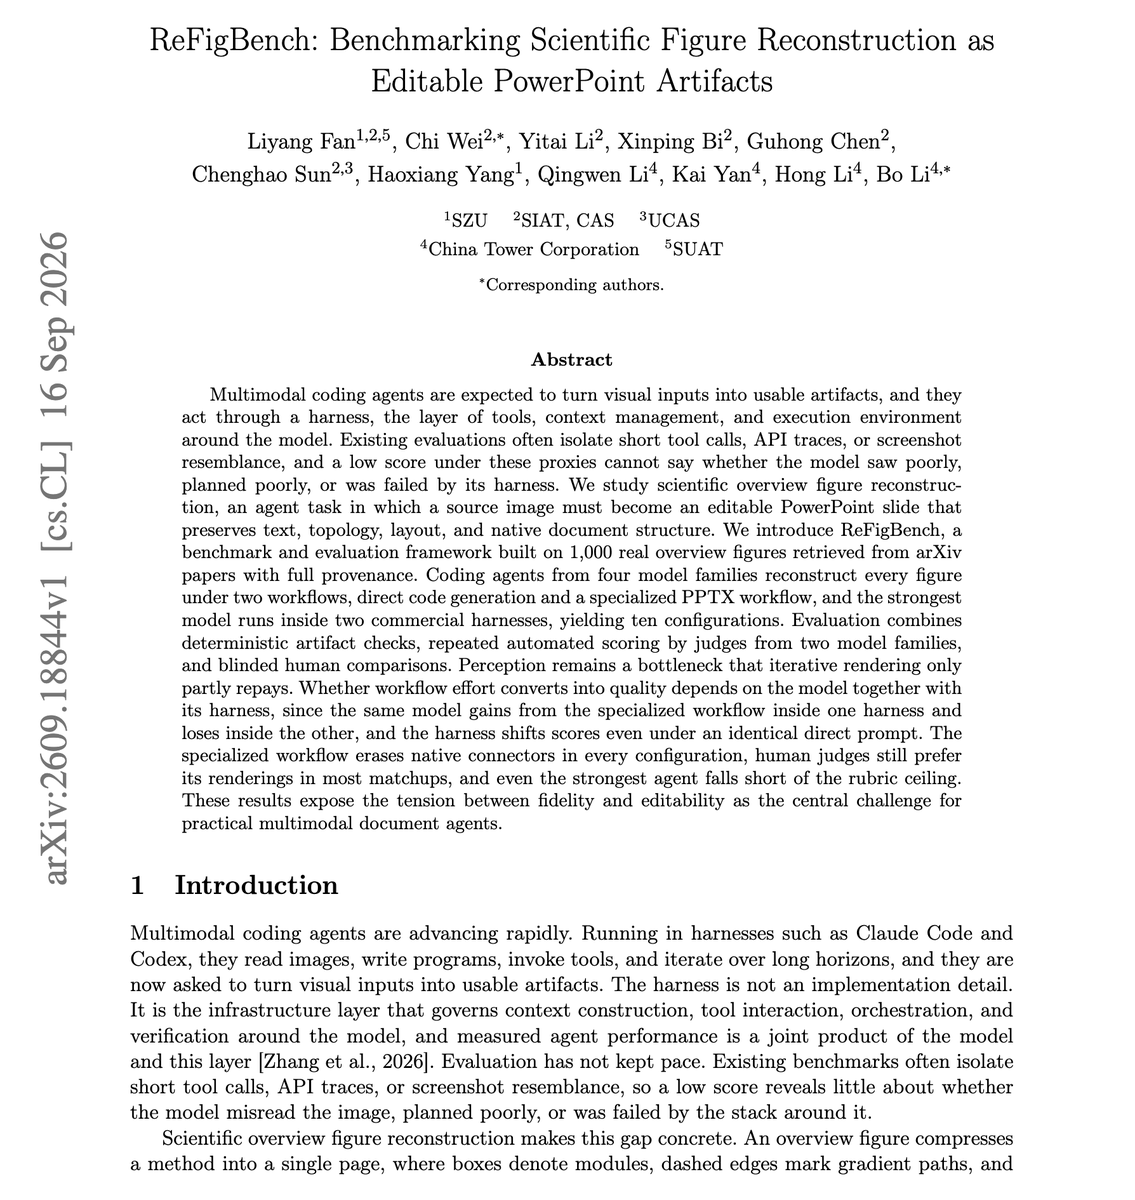
Impressive paper showing how much the harness changes a coding agent's results. Harnesses do play a huge role in what you are getting out of the models. GPT-5.5 was run inside both Claude Code and Codex on the same 1,000 tasks. With a specialized PowerPoint workflow, it improved inside one harness and got worse inside the other. The harness also changed scores when the prompt was identical. ReFigBench asks coding agents to rebuild real arXiv overview figures as editable PowerPoint slides…
open on x · 2 viewsViews and clicks count once per visitor per day. Clicks are opens of this post on X.