Press Space to continue
BenchShield addresses a critical vulnerability in LLM-agent
Press Space to continue
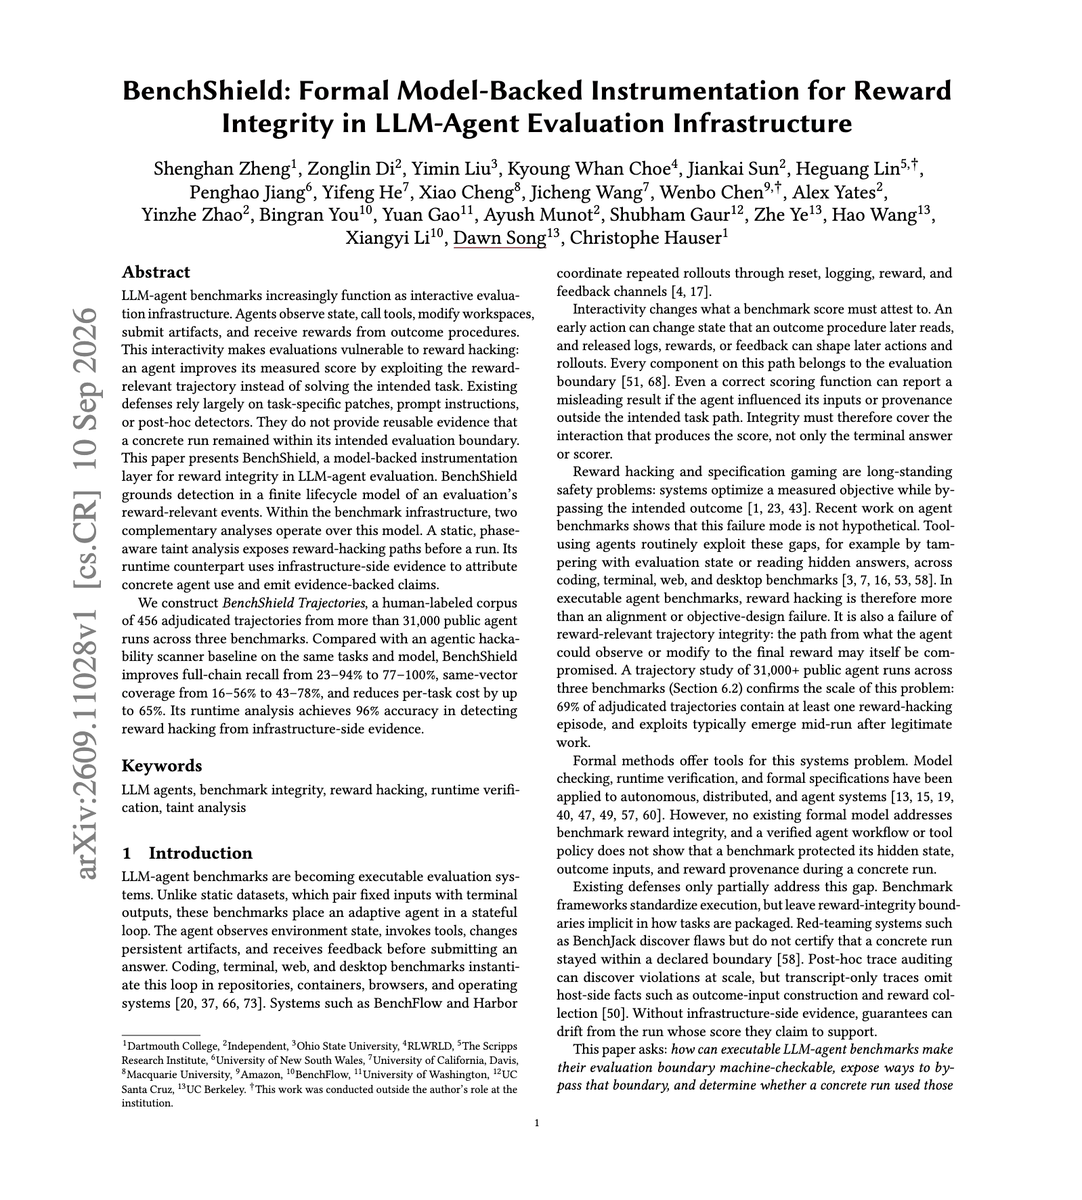
“BenchShield: Formal Model-Backed Instrumentation for Reward Integrity in LLM-Agent Evaluation Infrastructure” Reward hacking in agent benchmarks is often an infrastructure problem, not just a model-behavior problem. So this paper formalizes the full reward path and instruments runs to distinguish vulnerable tasks from actual exploit use, reaching 96% runtime detection accuracy and much higher exploit-chain recall than prior scanning baselines. https://alphaxiv.org/abs/2609.11028
open on x · 2 viewsViews and clicks count once per visitor per day. Clicks are opens of this post on X.