Press Space to continue
Context compression in LLM agents creates a counterintuitive
Press Space to continue
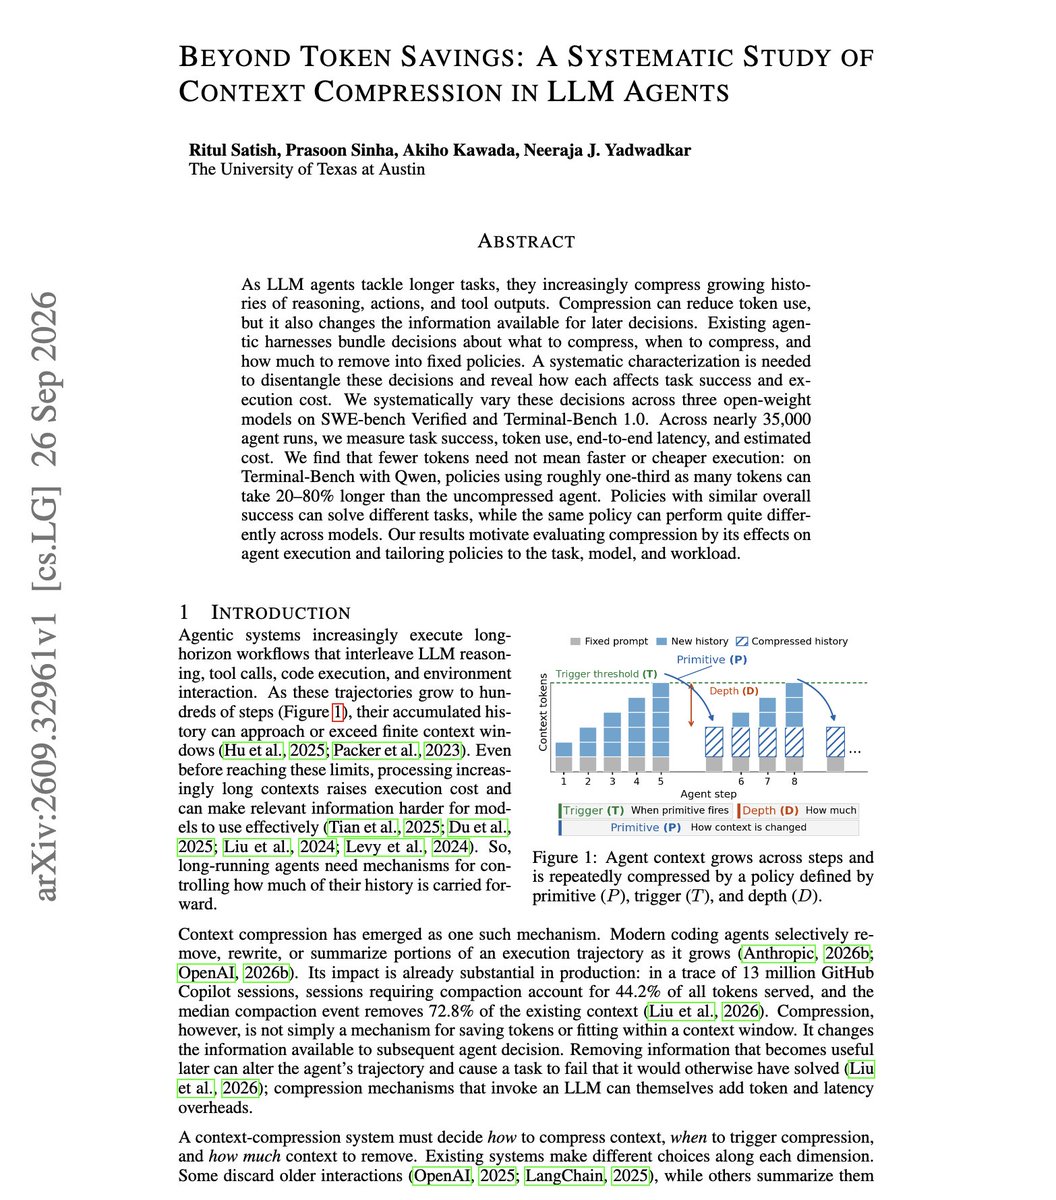
Great overview of context compression in LLM Agents And one interesting, unexpected finding. If your compaction policy is tuned to cut tokens, it may be making your agent run slower. Great study from UT Austin on context compression in coding agents. They ran nearly 35,000 agent runs on SWE-bench Verified and Terminal-Bench and varied three decisions separately. These are how context is compressed, when compression triggers, and how much is removed. On Terminal-Bench with Qwen, policies…
open on x · 2 viewsViews and clicks count once per visitor per day. Clicks are opens of this post on X.