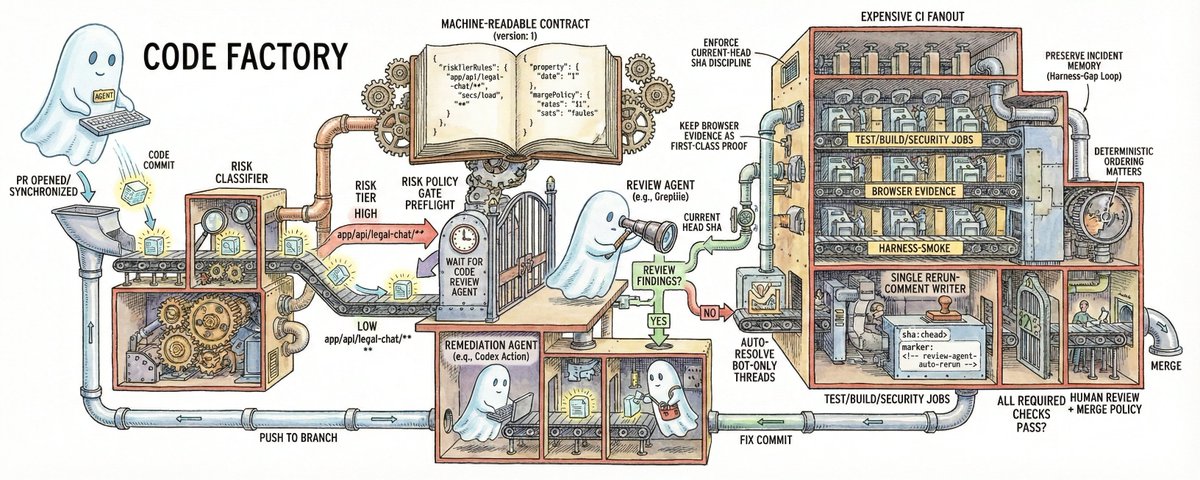
Evidence (tests + browser + review) is machine-verifiable
Findings turn into repeatable harness cases
The specific review agent can be @greptile, @coderabbitai, CodeQL + policy logic, custom LLM review, or another service. The control-plane pattern stays the same.
I took inspiration from this helpful blog post by @_lopopolo
The high-level flow
Keep one machine-readable contract
Your contract should define:
risk tiers by path required checks by tier docs drift rules for control-plane changes evidence requirements for UI/critical flows
Why it matters: it removes ambiguity and prevents silent drift between scripts, workflow files, and policy docs.
Gate preflight before expensive CI
A reliable pattern is:
run `risk-policy-gate` first verify deterministic policy + review-agent state only then start `test/build/security` fanout jobs This avoids wasting CI minutes on PR heads that are already blocked by policy or unresolved review findings.
Enforce current-head SHA discipline
This was the biggest practical lesson from real PR loops.
Treat review state as valid only when it matches the current PR head commit:
wait for the review check run on `headSha` ignore stale summary comments tied to older SHAs fail if the latest review run is non-success or times out require reruns after each synchronize/push clear stale gate failures by rerunning policy gate on the same head If you skip this, you can merge a PR using stale “clean” evidence.
When multiple workflows can request reruns, duplicate bot comments and race conditions appear.
Use exactly one workflow as canonical rerun requester and dedupe by marker + `sha:<head>`.
Add an automated remediation loop (optional, high leverage)
If review findings are actionable, trigger a coding agent to:
read review context patch code run focused local validation push fix commit to the same PR branch Then let PR synchronize trigger the normal rerun path. Keep this deterministic:
pin model + effort for reproducibility skip stale comments not matching current head never bypass policy gates
Auto-resolve bot-only threads only after clean rerun
A useful quality-of-life step:
after a clean current-head rerun auto-resolve unresolved threads where all comments are from the review bot never auto-resolve human-participated threads Then rerun policy gate so required-conversation-resolution reflects the new state.
Keep browser evidence as first-class proof
For UI or user-flow changes, require evidence manifests and assertions in CI (not just screenshots in PR text):
required flows exist expected entrypoint was used expected account identity is present for logged-in flows artifacts are fresh and valid
Preserve incident memory with a harness-gap loop
This keeps fixes from becoming one-off patches and grows long-term coverage.
What we learned running this in PRs
The most important lessons were:
Deterministic ordering matters: preflight gate must complete before CI fanout.
Current-head SHA matching is non-negotiable.
Review rerun requests need one canonical writer.
Review summary parsing should treat vulnerability language and weak-confidence summaries as actionable.
Auto-resolving bot-only threads reduces friction, but only after clean current-head evidence.
A remediation agent can shorten loop time significantly if guardrails stay strict.